FBI Open-Source Facial Recognition RFI (FBI-BSS-FRT): Two Accuracy Questions
Date: August 30, 2026 · Author: Dmitrii Zatona · Updated: September 29, 2026
TL;DR
- A September 2024 FBI request for information on open-source face recognition capabilities asks about accuracy twice, in items 4 and 6 of twelve numbered information items (Sections 1 and 2).
- Item 6 asks for results from NIST’s FRTE, whose measured object its design fixes: a named, dated algorithm build that NIST runs on sequestered galleries at operating points NIST chooses (Section 3).
- Item 4 asks for accuracy and error rates of the system used with the open-source data and names no metric, protocol, dataset or operating point, so the text cannot show whether both answers describe one object (Section 3).
- Comparable answers would need four choices made: identity ground truth, the gallery state behind a rate, the candidate-list parameters N, R and T, and what a transmitted template reveals (Section 4).
- Published methods cover much of this, from ISO/IEC 19795 to FISWG practitioner guidance, yet none of the documents reviewed, with 19795-6 read at abstract level, gives a ground-truth procedure for a gallery collected without enrollment-time identities (Sections 4 and 8).
- The analysis reads an information request on its own terms, finds no failure in it, and says nothing about any vendor, product, response or later acquisition (Section 8).
Two accuracy figures for face recognition search can be compared only if they describe the same measured object: the same algorithm build, gallery, operating point and type of evaluation. The FBI’s September 2024 market research on open-source face recognition capabilities asks respondents about accuracy twice. Item 6 asks for results from NIST’s Face Recognition Technology Evaluation (FRTE). Item 4 asks for “Specific information on accuracy and error rates” of the algorithm or system used with the open-source data. The first names an evaluation whose design fixes the measured object. The second names no metric, test protocol, dataset or operating point.
The published text does not let a reader establish whether two answers under those items would describe the same object, and none of the twelve items specifically requests the information that would settle it. It did not have to be requested, because the document is a request for information and makes no claim to be a performance specification. This article takes the question apart into the five elements an accuracy figure is about and the four choices a later evaluation would have to make, and checks which of them the reviewed documents supply.
1. What was published
The notice is FBI-BSS-FRT , “FBI BSS Facial Recognition Technology,” posted to SAM.gov on September 16, 2024 at 11:48 Eastern. SAM classifies it as a Sources Sought notice. Its single attachment titles itself “REQUEST FOR INFORMATION (RFI)” for “Open-Source Facial Recognition (FR) Capabilities” and runs to six pages, each under the letterhead of the FBI’s Finance and Facilities Division, Procurement Section. Requests for clarification were due October 1, 2024, and responses by noon Eastern on October 15, 2024, capped at fifteen pages including the cover page and table of contents. The notice archived automatically on October 30, 2024.
The record is plain. Its history holds one entry, the initial publication, and the search record shows zero modifications: no revision, no cancellation, no parent or related notice, and an empty award field. The record data carry no NAICS code, product service code or set-aside, while the same interface returns those fields for other notices. The attachment instead asks respondents to self-report “Applicable NAICS Codes.” The place of performance is Clarksburg, WV 26306. The point of contact is Brandon James, [email protected], listed on the PDF’s last page as “Contracting Point of Contact.” He is a procurement-section contact, and nothing below treats him as a program contact. The SAM description reproduces two sentences of mission context from the attachment’s background section and contains no measurement vocabulary.
The document says what it is, twice, in its own capitals (p. 2):
“THIS NOTICE IS FOR INFORMATIONAL PURPOSES ONLY. THIS IS NOT A REQUEST FOR PROPOSAL OR QUOTE. IT DOES NOT CONSTITUTE A SOLICITATION AND SHALL NOT BE CONSTRUED AS A COMMITMENT BY THE GOVERNMENT. RESPONSES IN ANY FORM ARE NOT OFFERS AND THE GOVERNMENT IS UNDER NO OBLIGATION TO AWARD A CONTRACT AS A RESULT OF THIS ANNOUNCEMENT.”
Page 5 repeats the statement and cites FAR 15.201(e). Everything below reads an information request on those terms. The notice was under no obligation to specify a metric, name a protocol or fix an operating point, and nothing here is a finding that it failed to. The question here is narrower and, for anyone who would have to answer such items, more practical. It is what, given the items as asked, would make the answers comparable with each other and with the one evaluation the document names.
As of September 29, 2026, the notice’s own record shows no continuation. Its related and award fields are empty, and it archived automatically on October 30, 2024. That negation is weak in both directions, because the notice’s own respondent form asks about GSA Schedule and NASA SEWP contracts, channels through which an order may proceed without a SAM notice.
This is the eighth teardown in a series; the previous one, FBI Image Capturing RFI: Which NARA FADGI Requirement Is Named, asked which referent a compound image-quality phrase names.
2. What the requirement says
The document’s scope is set in one sentence on page 2, the only place the output of the searched capability is described:
“Responses to this RFI are intended to identify capable parties who (1) conduct ongoing collection of open-source and publicly available images and (2) offer a face recognition (FR) capability to customers enabling them to search their face images against the collected open-source and publicly available images and receive a list of highest probably match candidates.”
The output phrase is quoted as printed, spelling included (sic). The stated downstream use of responses, on the same page, is that the information “may be used to support future acquisition strategies for competitive solicitations.” The eligibility sentence on page 3 reads:
“This RFI is open to any interested party with current capabilities to supply law enforcement customers with robust, open-source and publicly available face image repositories and functioning FR capabilities to search the repository.”
Responses are to identify the tools, search engines, capabilities and repositories that “must work in tandem” to provide the capability as Software as a Service. “Robust” and “functioning” are the only quality adjectives the document applies to the repository and the search capability. Twelve numbered information items follow:
| # | What it asks for |
|---|---|
| 1 | Company name, business size, proof of US base, SAM.gov registration |
| 2 | Evidence of technical ability, personnel, experience related to repository ownership and type of FRT used |
| 3 | ”Nature and source of the data available in the repository” |
| 4 | Accuracy and error rates of the FR algorithm(s) or FRT used with “the open-source data” |
| 5 | Unclassified submissions; proprietary areas marked |
| 6 | ”Any accuracy results” for the FRT from NIST’s FRTE program |
| 7 | Packaging, licensing terms, rough-order-of-magnitude and a-la-carte pricing |
| 8 | Any code developed outside the United States |
| 9 | Other assumptions and supporting information, one page maximum |
| 10 | Practices for data collection (including disclosure and consent), review, management, storage timeframes, monitoring |
| 11 | Whether search is possible without submitting an actual face photo, for example by “face image templating/encoding within the client owned IT boundary” |
| 12 | Up to three customer references, if possible |
The table shows that ten of the twelve items concern the respondent, its data practices and its commercial terms, and two concern measurement. Those two read in full:
“Specific information on accuracy and error rates of FR algorithm(s) or FRT used in the application in conjunction with the open-source data.”
“Provide any accuracy results for the FRT that would have been generated by National Institute of Standards and Technology’s (NIST’s) Face Recognition Technology Evaluation (FRTE) program.”
Two facts about the corpus are bounded by a full case-insensitive reading of the six pages and the SAM description. First, item 6 is the only reference to a standards body or an evaluation program anywhere in the notice or the attachment. The strings FRVT, ISO/IEC, EBTS, ANSI/NIST-ITL and FISWG do not appear. Neither do threshold, FMR, FNMR, FNIR, FPIR, 1:1, 1:N, rank, probability, gallery, probe, enrollment, benchmark or test protocol. Human review, audit, certification, training data, demographic, retention and the word “biometric” are absent too. “Accuracy” occurs twice, in items 4 and 6, “error rates” once, in item 4, and “candidate” once, in the scope sentence quoted above.
Second, and as a fact of form, “shall” occurs nine times. Every occurrence is directed at the response document, covering succinctness, classification marking, proprietary marking, pricing detail and page limits, or sits inside the boilerplate disclaimers. The single “must” is “must work in tandem,” about tools and repositories composing into a service.
That is the whole measurement vocabulary of the notice, and it is why the comparability question arrives this early. Item 6 attaches its request to an evaluation whose measured object the program’s design fixes. Item 4 attaches its request to “the open-source data,” a phrase that identifies whose data is meant and leaves open what would be measured on it, under which protocol and at which operating point. The text neither equates the two nor separates them, and it supplies nothing that would let a reader decide.
3. What an accuracy figure is a figure about
An accuracy statement about face recognition search is a statement about a tuple of five elements, and two statements are comparable only when their tuples agree where it matters. The five-part frame is an inference from ISO/IEC 19795-1:2021 and NIST’s FRTE reports, and no reviewed document lays it out in this form.
3.1 The five elements
- The algorithm build, a specific, dated software artifact, which a product name does not identify.
- The gallery: its provenance, composition and size N.
- The operating point: the rank limit R (or list length L) and the score threshold T at which errors are counted.
- The evaluation type: which class of test produced the figure.
- Who ran it, on whose data, and what was reported.
The third element is why an accuracy figure without an operating point cannot be compared with, or interpreted against, another. Identification metrics are parameterized as FNIR(N, R, T) and FPIR(N, T), and moving T trades one against the other. The fourth element comes from the standard itself. ISO/IEC 19795-1:2021 , the framework part of the biometric performance testing series, defines three evaluation types in its terms clause. A technology evaluation (3.13) is an offline evaluation of algorithms over a corpus. A scenario evaluation (3.14) measures end-to-end performance in a prototype or simulated application with a test crew. An operational evaluation (3.15) measures performance in a specific application environment with a specific target population.
The three types answer different questions. Treating figures from different types as inputs to one comparison, without matching their stated conditions, is the mismatch this frame exists to expose. That last step is an inference drawn here, and no clause of the standard states it.
3.2 What an FRTE result attests
The evaluation item 6 names is a technology evaluation in the 3.13 sense, and its design fixes its object. Participants submit their algorithms as compiled black-box libraries behind a C++ test interface that NIST specifies, and for that reason the identification report, NISTIR 8271 , does not describe how the algorithms operate (Executive Summary, p. 12). The six datasets are frontal and profile mugshots, desktop webcam photos, visa-like application photos, immigration lane photos and kiosk photos. NIST keeps them sequestered, so developers have no access to them for training or testing (p. 12). NIST chooses the enrolled population sizes and the operating points. It reports FNMR at a stated FMR for the 1:1 verification track and FNIR at a stated (N, R, T) for the 1:N identification track .
An FRTE result therefore attests one named, dated build’s behavior on NIST’s galleries at NIST’s operating points. By design it attests nothing about a gallery NIST did not run, and nothing about a hosted service, because the object under test is a library behind an interface and no deployment is tested. The report says as much about its own shelf life, describing FRVT reports as a snapshot of the capability current when they were written (p. 12).
Of the two tracks, 1:N identification is the one that fits a search returning a candidate list. Only there do the reported parameters FNIR and FPIR and the two reporting regimes appear. In the Identification regime the threshold T is greater than zero. In the Investigation regime the threshold is set to zero and the algorithm returns a fixed number of candidates. Verification reports different metrics for a different transaction, which is why the 1:N track carries the discussion below.
3.3 What item 4’s figure would be about
Item 4 gestures at elements 1 and 2, the algorithm or FRT “used in the application” running with “the open-source data.” Elements 3, 4 and 5 are unstated, and so are the gallery’s composition and size. If a future acquisition wanted an end-to-end claim about performance in a specific deployment against a specific population, ISO/IEC 19795-1 names that class: operational evaluation, term 3.15. The RFI does not say that item 4 means this. It also does not specifically ask respondents to state which type of evaluation produced their figure, by what method, against what ground truth, or for which gallery state.
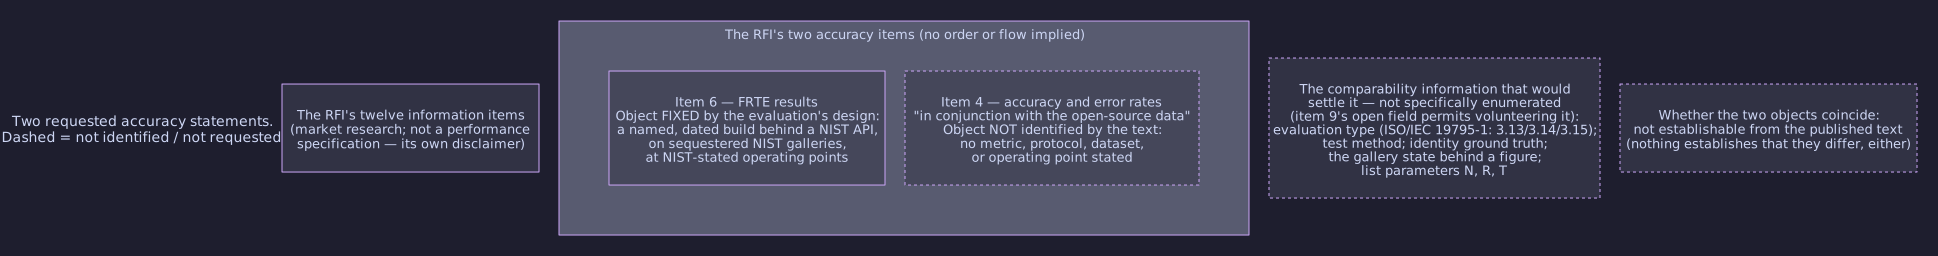
The diagram’s grouping is an inference from items 4, 6 and 9 of the RFI, ISO/IEC 19795-1:2021 and NIST’s FRTE documentation, not something the notice defines. It places the two items side by side and implies no order between them.
The finding, in its narrowest form, has three parts. Item 6’s object is known because FRTE fixes it. Item 4’s object is not identified by the text. The information that would put the two on the same footing, meaning evaluation type, method, ground truth and the gallery state behind a figure, is not specifically requested. Item 9’s open field for “any other assumptions, comments, or supporting information” permits a respondent to volunteer it, and no item asks for it. Nothing here establishes that the two objects differ. What the reviewed documents establish is that the published text does not let anyone determine whether they coincide.
4. Four comparability choices
Methods for the second kind of statement exist, and that changes the shape of everything after it. ISO/IEC 19795-6:2012, Testing methodologies for operational evaluation, is the part of the series on point. Per its published abstract it provides guidance on operational testing, specifies metrics for operational systems, details data that may be retained to monitor performance, and sets out test methods and recording and reporting rules. It is guidance-level for the test itself. ISO confirmed it in 2024, and since March 30, 2026 its catalog has listed it as to be revised.
At practitioner level, FISWG’s Face Recognition Systems Operational Assurance: Deployment Testing v1.0 supplies procedures that operate on the deployed gallery itself, such as extracting a fixed percentage of its enrollments for testing. That document is dated November 21, 2025, fourteen months after this notice, and appears here only as current methodological context and never as something the RFI could have named. The gap below is a matter of choosing among methods, since methods exist.
The four choices that follow are questions a future evaluation would have to answer.
4.1 Identity ground truth
The identification error metrics cited here, FNIR and FPIR as ISO/IEC 19795-1:2021 defines them, count errors against known mated and non-mated status. So do the deployment-testing procedures FISWG describes: its sampling presupposes groups known to be present in the deployed gallery. Where that known status comes from is the open question.
The RFI does not state how identities in a repository are established. Item 3 asks for the “Nature and source of the data available in the repository,” and as of September 29, 2026 no answer appears in the reviewed public record. That record therefore does not show whether such a repository carries enrollment-time identity assertions. If it does not, then none of the documents surveyed here supplies a procedure for establishing identity ground truth inside it. That is a conditional statement about a gap in methods, and it makes no claim about anyone’s data.
4.2 The gallery state behind a stated rate
Identification error rates are defined as functions of the enrolled population size N, which is what the (N, R, T) parameterization means. A stated rate is therefore a statement about a particular gallery state, and comparing two rates requires knowing the states each was measured on. That is a property of the metrics and says nothing about any repository’s contents. The RFI did not specifically ask for the gallery state behind a figure.
4.3 The returned list as a measurement object
For a candidate list to be measurable, the reviewed documents need three parameters: the enrolled population N, the list length or rank limit R, and the threshold T. ISO/IEC 19795-1:2021 defines rank as a candidate’s position in a list ordered by descending similarity score (term 3.24, paraphrased). FISWG’s Scoring Thresholds document (v1.1, November 4, 2022) gives the practitioner mechanics in the same terms: the user usually sets the list length, and candidates are sorted with the highest score first. The RFI’s output description fixes none of the three, and no reviewed document defines the notice’s output phrase as a reportable object.
One consequence depends on how an implementation builds its list, which the notice does not say. The RFI states neither a fixed-length list nor a threshold. If a system always returns a fixed number of candidates without applying a score threshold, then by a note in ISO/IEC 19795-1:2021, FPIR “is not a meaningful metric” for it. The false-positive half of “accuracy and error rates” would then have no defined metric until the list parameters are fixed. If the system applies a threshold, the metric is available and the threshold is part of the answer.
FRTE’s identification track reports both regimes because both are real. On one side are threshold-limited lists. On the other are 50 candidates returned at T = 0, where NIST states that “it is assumed and necessary that a human will be used to review the candidates” each search returns. The RFI states neither regime, so the notice does not show which branch applies to a given respondent.
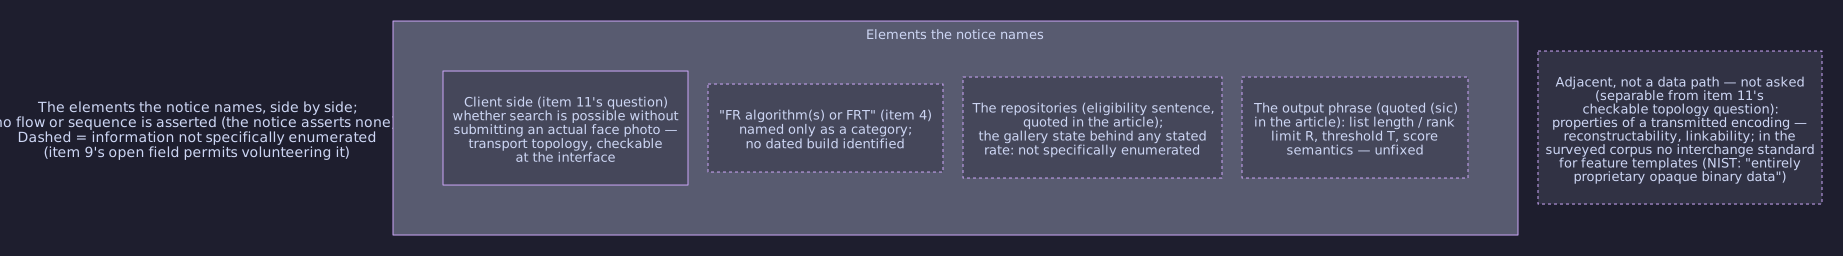
The diagram’s grouping is an inference from the scope sentence, the eligibility sentence and items 4, 9 and 11 of the RFI, not something the notice defines. It asserts no flow or sequence between the elements, because the notice describes none.
4.4 The template question is two separable questions
Item 11 asks whether searching is possible without submitting an actual face photo, and gives templating or encoding inside the “client owned IT boundary” as its example. That contains two questions, and they differ in how they can be answered.
The first is transport topology: whether a face photo leaves the client’s boundary, and what is transmitted instead. It is a property of the deployed integration and can be checked on its own terms by observing the interface. Nothing below weakens that, since a respondent can answer item 11 as asked and the answer can be verified independently of the second question.
The second concerns properties of the transmitted encoding: whether the original image can be reconstructed from it, and whether two encodings of the same person can be linked. The RFI does not ask about them, and here the reviewed documents take a specific shape. In the corpus surveyed, no document standardizes the content, format or interchange of face recognition feature templates. NIST gives the reason in the identification report (p. 20). The templates are proprietary, opaque binary data that carry much of each developer’s intellectual property, and the report concludes that “there is no prospect of a standard template.” Interoperability in automated face recognition, it adds, still rests on images and the documentary standards for them.
ISO/IEC 24745:2022 does define the property in question. Its term 3.26, irreversibility, describes a transform whose output “cannot be used to determine any information about” the data it was generated from. ISO/IEC 30136:2018 defines metrics for testing template protection schemes. In the texts retrieved, neither establishes a certification program or names a body that certifies a vendor’s template as irreversible. Both concern deliberately protected references, and no reviewed document states that an ordinary proprietary feature template has the 24745 property.
5. Scale
The figures below come from agency and peer-reviewed publications, each with the conditions under which it was measured. They are not set against one another. Each measures its own object, and no arithmetic is performed on any of them.
Enrolled population sizes in the FRTE 1:N evaluation. NIST’s identification report (NISTIR 8271 , draft supplement dated September 4, 2026) documents its own galleries in Table 1 (p. 30). Mugshot trials run at enrollment populations of 640,000, 1.6 million, 3 million, 6 million and 12 million subjects, one image each. The webcam trial runs 82,106 mated and 331,254 non-mated webcam searches against the 1.6 million mugshot gallery. A mugshot aging trial covers 3,068,801 enrolled subjects with 10,951,064 mated searches, and the report states a floor of 154,549 mugshot searches. These are NIST-held sequestered sets of stated provenance and type, and the numbers describe them and nothing else.
How error rates move with gallery size. The same report models the rank-based miss rate FNIR(N, R) as a power law in gallery size, aN^b (pp. 48–49). NIST notes that b is often much less than 1, which means FNIR grows only slowly as galleries get larger. Threshold-based miss rates follow the same law except at high thresholds, the ones that correspond to low FPIR. In the plotted results the exception shows at FPIR = 0.001, where the rates rise faster once N passes 3,000,000. The condition attached to that figure is the whole of its meaning, since it is measured on NIST’s mugshot enrollment sets at one stated false-positive operating point.
How much the input class matters. In the same evaluation, NIST reports FNIR(N, T) for webcam searches at around two to three times the mugshot values (p. 48). Two image classes, the same evaluation and the same algorithms produce that ratio.
One benchmark, two conditions. The peer-reviewed MegaFace benchmark (CVPR 2016) was built to vary one thing, the number of distractors in the gallery, and to measure the same algorithms under each condition. Algorithms above 95% on LFW, which the paper describes as the “equivalent of 10 distractors in our plots,” reach 35–75% identification rates with 1M distractors. The benchmark holds a million photos of more than 690,000 subjects. It is one paper’s measurement of the algorithms entered in its challenge, on its own gallery, ten years old, cited only because it isolates the gallery-size condition inside one controlled comparison.
Together these make a narrow point about the frame in Section 3. Within a single evaluation, a change of gallery size or of input class moves the reported figure. That is why an accuracy statement travels with its tuple, and why two statements whose tuples are unknown cannot be placed on one axis.
6. Privacy and oversight documents
What follows is a dated public record in two groups. The documents do not connect these groups to each other, and no reviewed document connects any of them to the RFI. No causal statement is made below, and none is available from these sources.
The privacy documents. Two DOJ/FBI Privacy Impact Assessments bracket the notice in time. The PIA for the FACE Operations Services , approved June 24, 2024, describes searches against “government photograph systems.” It states that the service does not search probe photographs against any private, public or non-governmental photograph system. The PIA for the NGI Interstate Photo System , approved November 7, 2024, describes a facial recognition search capability over photographs submitted with tenprint fingerprints. Both are cited as dated documents with their own stated scope. Neither mentions this notice, the notice mentions neither, and no inference is drawn here from their proximity in time.
The oversight record. GAO-21-518 , published June 3, 2021, examined federal law enforcement agencies’ use of facial recognition technology. Its recommendation-status record notes that the FBI issued a facial recognition procurement, tracking and evaluation policy directive in August 2022, and that in June 2025 it provided GAO with risk assessments for its use of multiple commercial facial recognition systems. GAO-23-105607 , published September 5, 2023, reviewed federal law enforcement use of commercial facial recognition services. Its recommendation-status record notes that the FBI finalized a Facial Recognition Technology Use Policy Directive in December 2023.
7. Who would build it
What is requested. The addressee is stated in the eligibility sentence: any party that, at the time of the notice, both maintains open-source and publicly available face image repositories and offers a search capability over them, delivered as a service. The response rules narrow the field further. Responses are capped at fifteen pages including front matter and may contain no proposals or offers, no past performance information or general descriptions of corporate experience, and no requests to be considered for award, and no response is taken by telephone. The Required Information block asks for the usual identifiers plus Facility Clearance if applicable, GSA Schedule and NASA SEWP Contract. The government “reserves the right to conduct demonstrations or follow-up with clarifying questions,” with no criteria stated for either.
What is documented. The oversight documents named in Section 6 record, as dates and directives only, that federal use of commercial face recognition services has been under review. No reviewed record establishes whether any vendor or service matches the full profile the eligibility sentence describes, and nothing in this analysis characterizes any vendor or product.
What is unproven. As of September 29, 2026, no reviewed public record shows whether anyone responded, how many did, what they submitted, or whether any of it informed a later acquisition. The notice states only that the information gathered “may be used to support future acquisition strategies for competitive solicitations.” Roles are not assigned here, because the public record assigns none.
8. What does not exist as a standard
Each row states the version read and its status relative to the notice date of September 16, 2024. Documents published after that date appear as current methodological context and never as something the notice could have named.
| Document (version, date) | Status at notice date | Fixes | Does not fix (bounded to this version) |
|---|---|---|---|
| NIST FRTE program, 1:1 and 1:N tracks; NISTIR 8271 (edition read: draft supplement 2026-09-04) | Program existed; this edition published after | What a result attests: a named, dated build behind a NIST interface, on sequestered NIST galleries, at NIST-stated (N, R, T) or FMR | Any vendor’s own repository; repository composition or provenance as an evaluated property; end-to-end behavior of a hosted service |
| ISO/IEC 19795-1:2021 , corrected version 2024-09 | Existed | The three evaluation types (3.13, 3.14, 3.15); identification metrics as FNIR(N, R, T) and FPIR(N, T); rank by descending similarity score (3.24) | Acceptance criteria or reference values for any application |
| ISO/IEC 19795-6:2012 (confirmed 2024; catalog status on 2026-09-25: to be revised since 2026-03-30; read at abstract level) | Existed | Per its abstract: guidance for operational testing; metrics for operational systems; retained data for monitoring; test methods and reporting rules | Per the retrieved text, no ground-truth procedure for a collected gallery; laboratory testing excluded by its stated scope |
| FISWG FRSOA: Deployment Testing v1.0 (2025-11-21) | Published after | Practitioner procedures on the deployed gallery, including sampling of enrollments for testing | Ground truth for enrollments whose identity was never asserted at enrollment |
| FISWG FRSOA: Identity Ground Truth v1.1 (2026-06-05) | Published after | A process for testing and repairing identity labels in a facial data set whose images are already linked to identities (§§ 1.1, 5.1.4) | Ground truth for a gallery whose images carry no identity labels to test |
| FISWG FRSOA: Scoring Thresholds v1.1 (2022-11-04) | Existed | Candidate-list mechanics for practitioners: list length set by the user, candidates sorted by descending score | A default list length, threshold, or score semantics for any deployment |
| ISO/IEC 39794-5:2019 ; ISO/IEC 19794-5:2011 | Existed | Extensible and legacy interchange formats for face image data, with conformance test assertions | Anything about feature templates |
| ANSI/NIST-ITL 1-2011: Update 2015 ; 1-2025 approved per the program page | Update 2015 existed; 1-2025 approved after | Transaction record types including Type-10 facial image records, with defined metadata fields | Template content or interchange |
| FBI EBTS v11.2 (2023-09-20); v11.3 (2025-06-05) | v11.2 existed; v11.3 published after | Rules for electronically transmitting biometric images to and from FBI systems, extending ANSI/NIST-ITL | Template interchange; the notice does not reference EBTS |
| ISO/IEC 24745:2022 | Existed | Irreversibility (3.26), renewability (3.33), and unlinkability, for protected biometric references | Any certification program or certifying body; any statement that an ordinary feature template has these properties |
| ISO/IEC 30136:2018 (catalog status on 2026-06-08: to be revised) | Existed | Metrics for testing template protection schemes | The protection schemes themselves; certification |
The table shows a corpus that fixes what an evaluation measured and how to report it, and leaves open what a vendor-held gallery must contain. The evaluation named in item 6 publishes its interface, its datasets’ provenance and sizes, its metrics and its operating points, and a result carries its conditions with it. The taxonomy separating that kind of measurement from a deployment measurement is standardized. So, at guidance level, is the methodology for the second kind, with practitioner procedures added since. A future evaluation wanting comparable answers would be choosing among published methods and would not have to invent one.
Four bounded negations follow, over the documents surveyed here: the FRTE 1:1 and 1:N track pages and NISTIR 8271 (2026-09-04 supplement); ISO/IEC 19795-1:2021, 19795-2:2007 and 19795-6:2012; ISO/IEC 39794-5:2019 and 19794-5:2011; the ANSI/NIST-ITL program page and 1-2011 Update 2015; FBI EBTS v11.2 and v11.3; ISO/IEC 24745:2022 and 30136:2018; and the FISWG published-documents list, with three documents read in full: Deployment Testing v1.0, Scoring Thresholds v1.1 and Identity Ground Truth v1.1, which repairs identity labels in a data set that already has them.
First, none of them, in the texts retrieved and with 19795-6 read at abstract level, supplies a procedure for establishing identity ground truth in a gallery assembled without enrollment-time identity assertions. Second, none defines criteria, metrics or conformance tests for a face image repository as a data asset, so no reviewed document gives the notice’s word “robust” any criteria. Third, none defines the notice’s output phrase as a reportable object; the parameters a candidate list needs, N, R and T, are defined, and the notice leaves them unfixed. Fourth, none establishes certification of irreversibility for a face template, or states that an ordinary proprietary feature template has that property.
Two accuracy questions sit two items apart on the same page of a six-page document. One points at an evaluation that publishes what it measured, on what, and at which operating point. The other points at data whose measurement conditions the text does not state. What separates the two kinds of answer is made of specific, published, selectable things: an evaluation type, a test method, a ground-truth procedure, the gallery state behind a figure and three list parameters. A market-research notice is entitled to ask its questions without settling any of them. This article does not claim that the two measured objects differ, that the notice should have asked more, or anything about any respondent, product or later acquisition. I work on verifiable evidence chains and provenance records in an adjacent area, and that work is separate from this analysis. More write-ups are on the engineering blog.
If an accuracy figure for a face recognition system will be compared with another one, designing the record of what was measured, on which gallery and at which operating point is contract work I take on.