FBI CJIS Data Mesh RFI: What Its Traceability Requirement Does Not Specify
Date: August 26, 2026 · Author: Dmitrii Zatona · Updated: September 29, 2026
TL;DR
- The FBI’s October 2024 market-research notice for a CJIS data mesh says that traceability of data used in model development and a clear audit trail will promote transparency and compliance (Sections 1 and 2).
- That sentence leaves five choices unmade: the audited object, its granularity, the versions kept, the event that writes a record, and the party who can verify it (Sections 2 and 3).
- A data product, the extract drawn from it, and a snapshot fixed at training time are three different audit objects with different records and failure modes (Section 4).
- No surveyed open form carries product identity, a binding to content, and an approval together across a system boundary; vendor platforms document approval inside their own boundaries (Sections 4 and 8).
- No related solicitation, award, or later notice was found in the public records searched through September 29, 2026 (Sections 1 and 6).
- The article does not read the preliminary sentence as a requirement and does not assert that any model consumes data from more than one domain (Sections 2 and 8).
The FBI’s Criminal Justice Information Services Division operates the country’s central law-enforcement data systems, and in October 2024 the Bureau posted a market-research notice for a data mesh there. The notice calls itself preliminary: it outlines requirements envisioned for a contemplated acquisition, not a specification. One of its sentences reaches further than the rest. After saying that the architecture should let each domain’s data scientists build and deploy models, the document adds that “traceability of data used in model development” and a clear audit trail will promote transparency and compliance.
Read as engineering, that sentence names a property and leaves five operational choices unmade. A document that calls itself preliminary is entitled to leave choices open, and the engineering interest is in what each choice involves. This article takes the sentence apart into those five choices and checks what existing open specifications express of each.
1. What was published
The notice is RFI-05292024 , “CJIS Data Modernization and Data Mesh,” posted on SAM.gov on October 25, 2024 by the FBI’s Finance and Facilities Division, Procurement Section, with responses due November 18, 2024. SAM.gov classifies it as a Sources Sought notice, while the attached seven-page document titles itself a Request for Information under FAR 15.201. Its point of contact is Contracting Specialist Tyler Cutright.
The archived SAM record contains one PDF attachment and no published Q&A attachment or amendment. The document’s own schedule invited questions by November 1 and said answers would follow by November 8. Two pairs of dates sit side by side in the record without explanation. The PDF’s title page reads 05/13/2024 while the notice posted on October 25, 2024, and the PDF’s submission deadline reads November 15 while the notice’s structured deadline reads November 18. The notice archived on December 3, 2024.
What followed is a bounded statement about public records. Searches through September 29, 2026 found no solicitation, award, or later notice that references this RFI, its Data Modernization Initiative, or its Data Services Value Stream. They covered SAM.gov by notice number, key phrases, and point of contact, and USAspending by keyword and awarding agency. The Department of Justice’s forecast of contracting opportunities , in its spreadsheet export dated August 27, 2026, lists no data-mesh or data-modernization requirement for the FBI. The limits are structural. The RFI itself asks respondents for GSA Schedule, GWAC, and NASA SEWP vehicles, and orders competed on such vehicles need not appear as public notices.
This is the fourth teardown in a series; the previous one, NIH N3C Data Enclave Sources Sought: What Crosses the Platform Boundary, asked whether an open-export requirement covers a reproducible research resource or only its data.
2. What the requirement says
The document states its own status in the introduction: responses may be used to formulate final requirements, and the description outlines preliminary requirements envisioned for the initiative. Its background describes a Data Mesh approach fostering a decentralized environment where individual domains own, manage, and curate their data. It names the CJIS Division’s data systems, NCIC, NTOC, NGI, UCR, NICS, and N-DEx, as the division’s context. The document lists those systems as background and assigns none of them to mesh domains, and the analysis here does not assign them either. The section headed as the contemplated requirement opens this way:
“This Section outlines the technical requirements for implementing a Data Mesh architecture within the FBI/CJIS. This approach prioritizes domain ownership, self-service data access, and decentralized governance.”
It then organizes the interest into five categories: data ingestion and integration, ETL and data pipelines, data storage and management, data governance and quality, and self-service analytics over data products exposed by domains. Each is an established product category, and the market the notice addresses ships all of them. The sentence at the center of this analysis comes two paragraphs later:
“The architecture should empower data scientists within each domain to leverage their domain expertise and readily available data to build and deploy models into production. Traceability of data used in model development and a clear audit trail will promote transparency and compliance.”
The modality is a fact of the text. The document says envisioned, contemplated, should, and will promote, and the requirement section does not say “shall” or “must,” words the same document uses for its submission instructions. A market-research notice is entitled to that register, and the analysis here does not read the sentence as a requirement. What can be read is what the sentence leaves out.
“Traceability of data used in model development” names a property without naming its object, which could be a data product, the specific extract drawn from it, or a snapshot fixed at training time. “A clear audit trail” names a record without naming the event that produces an entry or the party who can check one. Five operational choices sit inside those two phrases: object, granularity, retained versions, record-producing event, and verifier. The same document prioritizes domain ownership, self-service data access, and decentralized governance and speaks of data products exposed by domains, so those choices matter to the extent data products are exchanged between domains. The notice does not state that any particular model would consume products from more than one domain, and no such flow is assumed here.
The FBI TSC teardown, the first in this series, concerned record-level evidence for a particular predictive output. This sentence concerns the data used before a model exists. Neither property supplies the other, and nothing below reuses that analysis.
3. Five axes, six elements
Pricing the unmade choices takes a decomposition that the notice does not supply. The one used here is an inference from the notice’s model-development sentence, not something the notice defines. The five unchosen choices act as axes over six artifact elements:
| Axis (unchosen choice) | Elements it acts on |
|---|---|
| Audited object | (1) data-product identity/version; (2) training extract/snapshot |
| Granularity | (2) |
| Retained versions | (1), (2), (3) transformation/run identity |
| Record-producing event | (3), (4) model-build association |
| Verifier | (5) ownership/approval assertion; (6) audit-record retention/verifiability |
The table maps each choice to the artifacts it would change, and the choices overlap on the training extract. The literature that the notice’s vocabulary evokes leaves the same choices open. In the two defining data-mesh articles (2019 , 2020 ), lineage and provenance come up in five places. They appear as catalog metadata, “data provenance and data lineage as the metadata associated with each data product,” and as unelaborated items in lists of platform capabilities and enforced traits. “Data product versioning” appears once, undefined, and the words “audit” and “trail” occur in neither text.
Governance in that literature is federated and computational, “automated execution of decisions by the platform.” That names an executor for governance decisions and, in the two texts scanned, no record semantics for them.
The diagram’s decomposition of the training path is an inference from the notice’s model-development sentence, not something the notice defines.
4. Three questions the sentence leaves open
The five axes group into three engineering questions, and each subsection takes one. The first is what object is audited. The second is which event writes a record and who can check it. The third is what has to travel when a data product crosses from one domain to another.
4.1 “Data used in model development” does not define its object
Three readings of the phrase produce three different engineering artifacts. If the object is the data product, traceability means a record that model M consumed product P. That record is silent about what P contained when M was trained, since products update. If the object is the extract, traceability means recording what was drawn, and what that record survives depends on its form. An extract kept as a query plus identifiers can be re-run against data that has since changed, while an extract kept with its values or their fixity preserves what was read.
If the object is a snapshot, the training body fixed at a point in time, traceability means content that can be re-identified later. That requires a fixity mechanism, such as a hash, a frozen copy, or a version pin, which the product reading does not need. The consequence runs downstream. An audit trail over products is a different artifact from an audit trail over snapshots, with different storage and different failure modes, and a reviewer who holds one cannot answer questions posed against the other. The notice’s phrase is compatible with all three readings. Nothing in the document selects one, and the five categories name governance and quality but not versioning.
4.2 “A clear audit trail” does not define the event or the verifier
An audit trail is a sequence of records, and two definitions make it an engineering object: which event produces a record, and who can check the result. Candidate events multiply in a mesh vocabulary. A product’s publication, a consumer’s subscription, an extraction, a training-run start, and a model’s deployment could each write an entry. The notice names none. It names no reader either, whether a domain’s own engineers, a central governance function, or a party outside the operator, and each of those implies a different record design.
A shipped ML stack shows the difference between having records and having chosen those two definitions. MLflow, a widely deployed open-source tracking and registry platform, records training inputs with a digest and links registered model versions to their producing runs (“You can trace back exactly how a model was trained,” per its model registry documentation ). Inside one deployment it covers elements 2 through 4 of the model above. The same product’s REST API documents runs/delete, runs/update, and model-versions/delete.
That is a documented example of a provenance record that the operator controls and can change. No reviewed MLflow documentation defines a verifier-facing assertion or a retention rule. A tool that never promised those things has no defect here. The gap between such a record and an audit trail with chosen event and verifier semantics consists of the two definitions the contemplated sentence has not made.
The notice adopts none of the following, and none of it defines the notice’s phrase; it shows what chosen audit semantics look like elsewhere. NIST SP 800-53 frames the choices as organization-defined assignments. AU-2 has the organization identify the “organization-defined event types that the system is capable of logging,” AU-12 assigns which components generate records, and AU-9 requires protecting audit information from modification and deletion.
The FBI’s own CJIS Security Policy , version 6.1 of June 25, 2026, governs systems that handle criminal-justice information and is not referenced by this RFI. It fills those assignments in. Its event list extends to attempts to access, modify, or destroy the audit log file itself, and it sets content requirements and retention of audit records for “a minimum of one (1) year.” NIST’s AI Risk Management Framework , a voluntary framework, names the motivation at the training-data level: “Maintaining the provenance of training data … can assist with both transparency and accountability.” Selected audit semantics exist, down to the retention figure, and selecting them is the step the contemplated sentence has not taken.
4.3 The conditional handoff
The third question exists to the extent data products are exchanged between domains. The condition comes from the notice’s own vocabulary of domains that own, manage, and curate their data and of data products exposed by domains, and the analysis adds no assertion about actual flows. When an exchange happens, whatever crosses either carries the traceability or does not, because the consuming side’s records can only reference what arrived. Three things would need to travel: the identity and version of the product, some binding to content, and whatever ownership or approval assertion the governance model wants downstream. The survey question is which open, cross-system forms exist to carry them.
The specifications here are younger than in any earlier article of this series, and the survey found real coverage with specific holes. The Linux-Foundation-stewarded Open Data Product Standard (Bitol, v1.0.0) is the closest data-product interchange form. It is a YAML document with product identity, status, and ports whose inputs are pinned by data-contract id and version. Per its own field tables, it carries no approval or attestation fields, no binding to content in the form of a hash of data or schema, and no runtime records, only declared design-time dependencies. Version 1.1.0, released in September 2026, adds no approval, attestation, or hash fields.
Its companion, the Open Data Contract Standard (v3.1.0), versions the contract document (“Current version of the data contract.”) and defines no field for the version of the data served under it. Its only approval fields name the approvers of access roles, and it defines no lineage, provenance, or audit fields; v3.2.0 of September 2026 keeps both properties. One documented deprecation bears on lineage. The Data Contract Specification (v1.2.1), the one contract format with a field-level lineage object, was deprecated by its authors in favor of ODCS, which has none.
Vendor implementations document more than the specifications do, each inside its own boundary. AWS DataZone documents data products as first-class objects whose API revisions pin member-asset revisions, and a subscription workflow whose requests are approved, rejected, or revoked. Its lineage is versioned with each event (DataZone lineage ), and the durable audit copy lands in an operator-owned bucket through CloudTrail. Collibra documents a product lifecycle in which “designated stakeholders must approve it” (Collibra data products ) and contract manifests in ODCS form (Collibra data contracts ). The approval is a platform workflow state, and ODCS’s schema defines no field for it in the interchanged document.
Databricks documents a catalog per business domain as a pattern that “aligns with data mesh architectures and domain ownership” (Unity Catalog deployment guide ), with lineage aggregated across all workspaces attached to the metastore (Unity Catalog lineage ). That configuration cuts against any assumption that decentralized ownership implies decentralized record-keeping, since a mesh can centralize its lineage collection. Starburst documents export and import of product definitions as YAML in its own schema (Starburst data products ).
Across the four, approval semantics exist without interchange (DataZone, Collibra), and interchange exists without approval (Bitol ODPS, Starburst). No surveyed form carries identity, content binding, and approval together across a system boundary. That negative is bounded by the specifications and vendor pages named in this section, as of September 29, 2026.
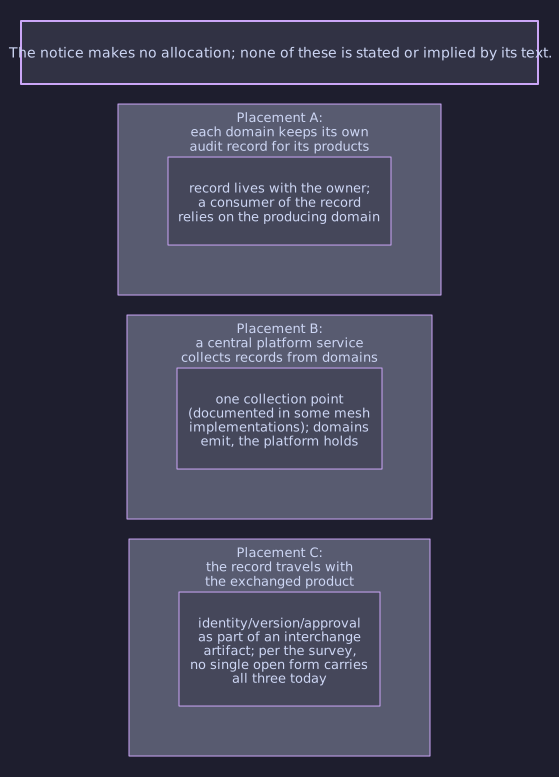
The diagram’s three placements are an inference from the notice’s mesh vocabulary and the vendor documentation above, not something the notice defines; the notice allocates the record to no one.
5. Scale
The division whose data operations form this notice’s background publishes its own magnitudes, quoted here as context with their dates and put to no further use. NCIC holds more than 18 million active records across 22 files, per the FBI’s NCIC page as of 2023. The CJIS Division’s Acting Assistant Director put NCIC’s traffic at “an average of 10 million daily transactions” in December 2024 testimony .
NICS processed 26,123,215 background checks in 2025 per the FBI’s own statistics , figures the same document says “do not represent the number of firearms sold.” The NGI fact sheet for August 2026 lists a criminal repository of 88.5 million fingerprint composites and roughly 25,000 submitting partners that month. The UCR program received 2025 data from more than 17,000 agencies covering 96.2 percent of the population (FBI release ). These are the published magnitudes of the division’s existing systems, named in the notice as background, and the notice does not connect them to the contemplated mesh.
6. The procurement record
The record around the notice is thin and datable. The RFI’s background names an organizational anchor: the division established an agile Value Stream, the Data Services Value Stream, dedicated to this Data Modernization effort. The division’s own 2024 Year in Review records the same event, stating that CJIS IT staff “established the Data Services Value Stream in support of the 2030 vision.” That text comes from an Internet Archive snapshot of June 23, 2025. It is the one public FBI document located that uses the term.
The notice itself was posted once, never amended, and archived after 39 days, and the searches described in Section 1 found no related document since. The public record does not say whether market research this old still feeds an active acquisition plan. The RFI’s own introduction reserved that possibility, to formulate acquisition strategies for competitive solicitations, and the record goes no further than the reservation.
7. Who would build it
The notice describes its intended respondents concretely. They are vendors of commercial off-the-shelf software deployable in government cloud environments, since FBI/CJIS prioritizes COTS that reside in a Government Cloud. They hold GSA Schedules, GWACs, or NASA SEWP vehicles, can offer test licenses for up to 120 days in a non-operational environment, and can describe licensing and subscription pricing for budget assessment.
That is what the notice requests: commercially available platforms and software for the five categories of Section 2, deployable in a government cloud, with pricing and trial terms. Public records do not show which vendors responded or whether any acquisition strategy followed (Section 1). The survey adds a bounded point. Shipped products exist for the five categories. For the object, event, and verifier of the model-development sentence, the reviewed specifications and vendor documents define no defaults, and those definitions are not among what the surveyed forms carry.
8. What does not exist as a standard
The per-element survey starts with the form that comes closest. CycloneDX , the OWASP bill-of-materials standard whose 1.5 release added a machine-learning BOM, covers the most at once. It types components as models and data with versions and content hashes, and its model card structure lists modelParameters.datasets as “The datasets used to train and evaluate the model.” It adds formulation workflows that describe how a component came together, machine-readable data governance with owners, custodians, and stewards, signable documents, attestations with signatories, and cross-document references that let one BOM cite an element of another. A portable, signed container for a declared association between model and data therefore exists.
The schemas of CycloneDX 1.6 and 1.7, inspected field by field, leave four things undefined. There is no immutable-snapshot semantic, since the inline dataset form carries no version or hash fields at all. There is no observed-run identity, since formulation is an author’s declaration with no contract that its timestamps reflect an execution. There is no approval predicate, since attestations assert conformance to named standards and “owner approved dataset version V for training model M” has no defined form. There is no retention rule for the records themselves.
| Element (author’s model) | Closest open form (version) | What the spec text lacks |
|---|---|---|
| 1. Product identity/version | CycloneDX 1.6/1.7 component version+hashes+BOM-Link; ODPI ODPS 4.1 productVersion; Croissant 1.0 semver+sha256 | ODCS 3.1.0 versions only the contract document; the dataset version of OpenLineage (core 2-0-2, spec at commit 7a84fd4d) is one opaque string |
| 2. Training extract/snapshot | DVC lock-file hashes; MLflow dataset digests | No surveyed spec defines an immutable-snapshot semantic; CycloneDX’s inline dataset form has no version/hash fields |
| 3. Run identity | OpenLineage runId + source-code facet (git SHA); MLMD executions | Run ids meaningful only against one collector or store |
| 4. Model-build association | MLMD events (“Which training run led to this model?”); MLflow registry links | Inside one operator-local, mutable store; OpenLineage’s 38 standard facet schemas contain no model concept |
| 5. Ownership/approval | CycloneDX data governance + attestations; OpenLineage ownership facets | Owner labels without approval; no defined approval-of-use predicate anywhere surveyed |
| 6. Record retention/verifiability | Sigstore model-signing v1.1.1; signed BOMs | Signatures cover model bytes or documents; no surveyed spec defines retention for traceability records |
The table and Section 4.3 name each specification with the version inspected. As of September 29, 2026, no open specification among them defines all six elements as interoperable record semantics across system boundaries. The elements individually are in better shape than this series has found in any earlier domain. MLMD links a model to the training run that produced it inside one store, DVC pins training bytes inside one tool, and CycloneDX signs and ships the declared association.
What the five axes of Section 3 need, and no surveyed form supplies together, is a connective set: a snapshot that stays what it was, a run that identifies itself, an approval that travels, and a record checkable by whichever verifier the fifth axis turns out to name. The surveyed forms leave that last choice as open as the notice does. Each of the five choices changes what the resulting records can answer, and the verifier also changes whom the records are for. A future solicitation may make those choices, and this market research may inform it; as of the searches in Section 1, no public record shows that any of them has been made.
This article does not read the preliminary sentence as a requirement, does not claim that any model consumes products from more than one domain, and does not evaluate the division’s programs. I work on verifiable provenance for derived outputs in this area, and that work is separate from this analysis. More write-ups are on the engineering blog.
If trained models will later have to show which data snapshot they were built from and who approved its use, designing that trail is contract work I take on.